A job queue in Postgres: how FOR UPDATE SKIP LOCKED lets workers share a table
Build a simple, safe job queue on Postgres: claiming rows with SKIP LOCKED, handling crashes with leases, retries, and the limits of the approach.
Many applications need a background job queue: send this email, resize that image, call this slow API. The first instinct is to add a broker. Often you already have a perfectly good place to keep jobs, and it is your database.
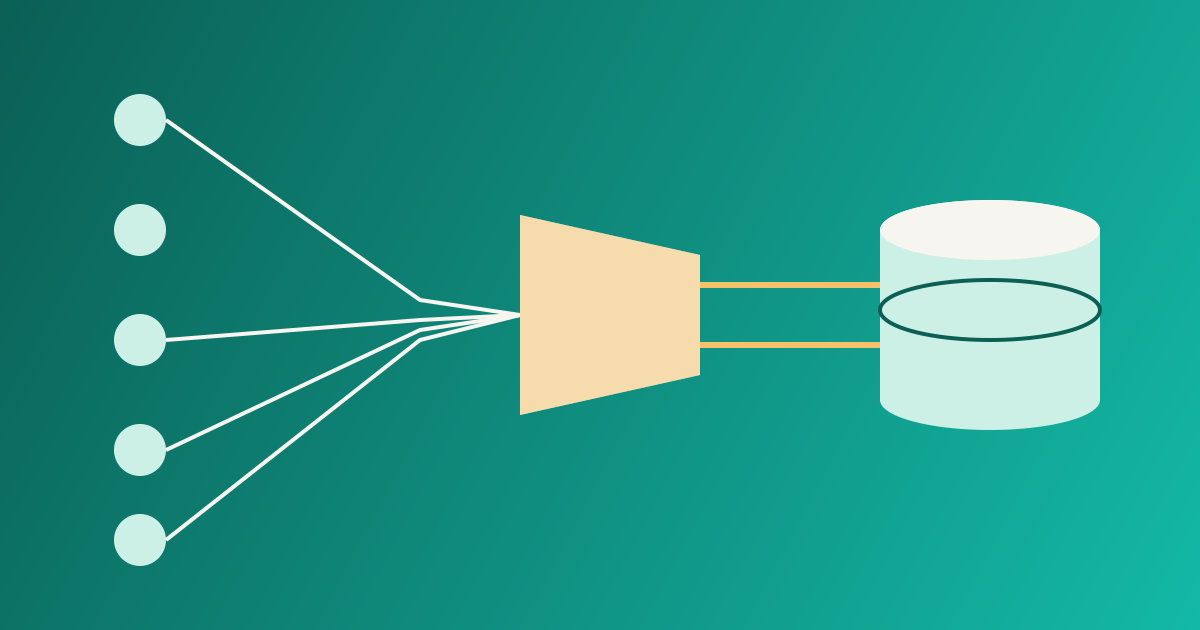
The hard part of a queue in a database is letting several workers pull jobs at once without two of them taking the same one. Postgres has a clause for this.
The problem with the obvious query
The naive version looks like this:
SELECT id, payload FROM jobs
WHERE status = 'pending'
ORDER BY id
LIMIT 1;
Run it from ten workers and they all see the same first row. Adding FOR UPDATE makes the others wait for the lock, so the work is safe but serialized: nine workers stand in line behind one.
SKIP LOCKED
The PostgreSQL SELECT documentation describes two options for rows that are already locked. NOWAIT raises an error. SKIP LOCKED simply leaves out any selected row that cannot be locked right now. Each worker then gets a different row and nobody waits.
BEGIN;

SELECT id, payload
FROM jobs
WHERE status = 'pending'
ORDER BY id
LIMIT 1
FOR UPDATE SKIP LOCKED;

-- do the work, then:
UPDATE jobs SET status = 'done' WHERE id = $1;

COMMIT;
The documentation is clear that skipping rows gives an inconsistent view of the data, so this is not meant for general queries. Its stated use is exactly this one: avoiding lock contention when several consumers read a queue-like table.
The catch: long transactions
The version above holds a transaction open for the entire duration of the job. That has costs. A job that takes a minute holds a connection and a transaction for a minute, which matters if you run behind a pooler (see what PgBouncer's pool modes change). Long transactions also hold back vacuum.
A better shape is to claim quickly, commit, work outside the transaction, and report the result in a second short transaction. For that you need a lease.
Claiming with a lease
Add two columns: when the job may next run, and how many attempts it has had.
ALTER TABLE jobs
  ADD COLUMN run_after timestamptz NOT NULL DEFAULT now(),
  ADD COLUMN attempts int NOT NULL DEFAULT 0;
Now the claim is a single statement that moves run_after into the future:
UPDATE jobs SET
  status = 'running',
  attempts = attempts + 1,
  run_after = now() + interval '5 minutes'
WHERE id = (
  SELECT id FROM jobs
  WHERE status IN ('pending', 'running') AND run_after <= now()
  ORDER BY run_after
  LIMIT 1
  FOR UPDATE SKIP LOCKED
)
RETURNING id, payload;
The worker commits immediately and starts working. If it finishes, it sets status = 'done'. If it crashes, nothing needs to happen: after five minutes the lease expires, run_after is in the past again, and another worker picks the job up. Pick a lease longer than your slowest normal job, or have long jobs extend their own lease.
An index that matches the query keeps the claim cheap:
CREATE INDEX jobs_ready ON jobs (run_after)
WHERE status IN ('pending', 'running');
Retries and failure
Because a crashed job can run twice, jobs must be safe to repeat. That is the same rule that applies to API retries, covered in idempotency keys: give each job a stable key and make the side effect check it.
For failures the worker can see, a few rules go a long way:
- On error, set
run_afterto now plus a growing delay, and add some randomness so retries do not all land together. - After a fixed number of attempts, set
status = 'failed'and keep the row. A person should be able to look at it. - Record the last error text in a column. It saves a lot of log searching.
Producing jobs safely
If the job should only exist when some other change commits, insert it in the same transaction as that change. This is the same trick as in the transactional outbox, and it is the strongest argument for keeping the queue in the database: enqueueing is atomic with your data for free.
Warning
Be careful about creating jobs from inside schema migrations. A migration can run more than once or against a copy of the data, and the jobs it creates will run against whatever is there.
Where it stops working
A Postgres queue is a good fit for thousands of jobs per second at most, and for many applications far fewer is plenty. Think about a dedicated broker when:
- You need very high throughput or fan-out to many independent consumers.
- Job payloads are large and short-lived, so queue churn creates a lot of dead rows.
- You need streaming semantics, such as replay from an offset.
Dead rows are the one to watch. A table where every row is inserted, updated a few times and deleted creates work for autovacuum. Delete finished jobs in batches, or partition by day and drop old partitions.
A short checklist
- One short claim transaction with
FOR UPDATE SKIP LOCKED. - A lease column so crashed workers do not strand jobs.
- Idempotent job handlers.
- A capped number of attempts and a visible failed state.
- Regular cleanup of finished rows.
That is most of what a small queue needs. You can add a broker later if the numbers ask for one, and your job handlers will not change.