How database indexes speed up reads, and when they slow down writes
Learn when to use indexes for faster queries and when they hurt write performance.
Understanding Database Indexes: The Good, the Bad, and the Practical
Think of database indexes like the index at the back of a technical book - they let you skip straight to the section you need instead of flipping through every page. But like any tool, they come with trade-offs. Well-placed indexes can make read queries lightning-fast. Poorly chosen ones? They'll bog down writes and eat up storage space.
Let's look under the hood at how indexes really work, when they're worth it, when they're a burden, and how to make smart calls in production.
How indexes actually work
When you run a query like SELECT * FROM users WHERE email = '[email protected]', the database has two options:
- Full table scan: Go through every row, check the
emailfield, and return matches. - Index lookup: Use an index to zero in on the matching row directly.
Without an index, it's a brute-force search through every record. But with a B-tree index - the most common kind - the database keeps a sorted structure where each entry links to a row. This lets it find a value in logarithmic time, which is way faster than reading everything.
For instance, if your users table holds 1 million rows and you've indexed email, the database can pinpoint the right record in roughly 20 steps (since log2(1M) 20), not a million.
When indexes make sense - read-heavy traffic
Indexes really pay off when you're doing repeated lookups on specific columns. Imagine a user dashboard that pulls recent orders. If you regularly run:
SELECT * FROM orders WHERE user_id = 123 ORDER BY created_at DESC LIMIT 10;
An index on user_id - and maybe created_at too - lets the database quickly locate all orders for user 123 and sort them without touching the entire table.
Keep this rule in mind: Index columns used in WHERE, JOIN, ORDER BY, and GROUP BY clauses.
But don't get carried away. Every index adds cost to every write operation.
The hidden cost - write slowdowns
Every time you insert, update, or delete a row, the database must also update every index on that table.
Say you insert a new user with an index on email:
- Add the row to the table.
- Insert the email and its pointer into the B-tree index.
- Rebalance the tree if needed.
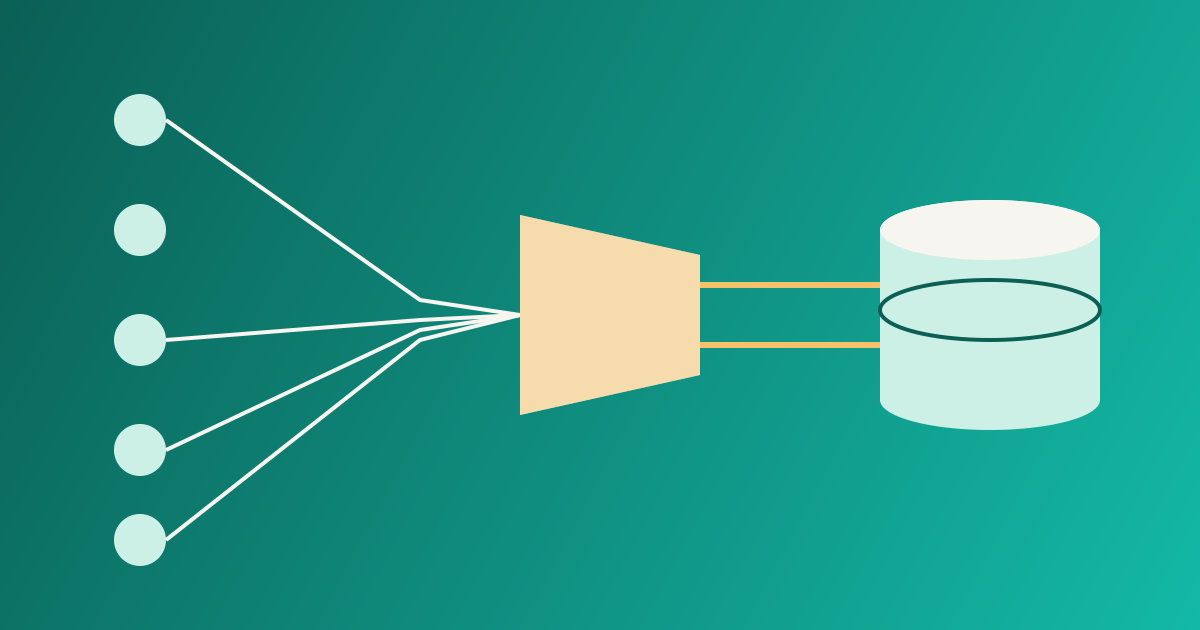
More indexes mean more work per write. This adds up fast, especially during bulk imports, batch jobs, or high-volume API traffic.
When indexes become a liability - write-heavy systems
Picture a logging service that writes 10,000 entries per second. Each log entry has five indexes: one on timestamp, one on level, one on service, one on host, and one on message.
That's five index updates per write. In practice, this can cut write throughput in half - or worse - because the database spends most of its time keeping indexes in sync, not serving data.
In such scenarios, consider:
- Keeping just a single index on
timestampfor time-based queries. - Avoid indexing high-cardinality columns like
messageoruser_agentunless absolutely needed. - Offload query-heavy workloads to a separate analytics database where you can use heavier indexing.
Real-world indexing tactics
1. Focus on the query, not the column
Don't slap an index on a column just because it's "important." Ask: Which queries are slow? What conditions do they use?
Use EXPLAIN (or the equivalent) to check how the query runs. If you see Seq Scan (full table scan) on a large table, an index might fix it.
2. Build composite indexes, not individual ones
When you often filter on multiple columns together, combine them into a single composite index.
Instead of:
CREATE INDEX idx_user_id ON orders(user_id);
CREATE INDEX idx_status ON orders(status);
Do:
CREATE INDEX idx_user_status ON orders(user_id, status);
This one index can support queries like:
SELECT * FROM orders WHERE user_id = 123 AND status = 'pending';
But remember: column order matters. The index works best when the query filters on the leading columns.
3. Don't go crazy with indexes
A safe target: 3 to 5 indexes per table in production. Beyond that, write performance starts to degrade.
To decide, measure:
- Write latency under real load.
- Index size (use
pg_total_relation_sizein PostgreSQL or similar). - Query speed before and after adding an index.
4. Handle index maintenance
Indexes grow over time. B-trees can get unbalanced, leading to slower lookups.
In PostgreSQL, VACUUM helps clean up dead tuples and keeps indexes healthy. In high-write setups, schedule VACUUM during off-peak hours or ensure autovacuum is properly tuned.
5. Use partial indexes for focused queries
If you only query a small fraction of data often, use a partial index.
For example, if only active users are queried:
CREATE INDEX idx_active_users ON users(email) WHERE status = 'active';
This index is smaller, faster to update, and skips inactive users that rarely show up in queries.
6. Drop unused indexes
Indexes that sit idle are dead weight.
Check usage with tools like:
pg_stat_user_indexesin PostgreSQL.sys.dm_db_index_usage_statsin SQL Server.- Review query logs for unused indexes.
If an index shows zero scans or seeks over weeks, it's probably safe to remove.
Case study: E-commerce order system
You manage a store processing 500 orders per minute. Common queries include:
- Recent orders by customer.
- Orders filtered by status (e.g., shipped, pending).
- Orders in a date range.
Start with:
-- Cover common queries
CREATE INDEX idx_orders_user_status ON orders(user_id, status);
CREATE INDEX idx_orders_created_at ON orders(created_at);
Now suppose you add a feature where customers can rate orders, and you frequently query ratings.rating_value.
With 100,000 active users and 10 ratings per second per user, that's 1 million writes per minute. Each write needs index updates.
Instead of indexing rating everywhere, consider:
- Using the index only for analytics dashboards, not real-time queries.
- Using a materialized view or a dedicated reporting table for reporting needs.
Final takeaway: Measure, don't assume
The best indexing strategy comes from real data, not assumptions.
- Run actual queries under realistic load.
- Use
EXPLAIN ANALYZEto see real execution times and plans. - Track write latency and index size over time.
- Reassess indexes every few months - especially after schema changes.
Indexes aren't free. They trade storage and write speed for faster reads. The goal is balance: add only what's needed, and remove what's not.
If you're unsure, ask: Is this index used by a query that runs often enough to justify the cost?
If not, skip it. Your database will run smoother - and you'll sleep better.